What is Jev: TypeSafe AI's model that decides instead of writing
What is Jev, TypeSafe AI's System One model: it returns typed decisions with probabilities instead of text. How to call its API, what it costs and when to use it.
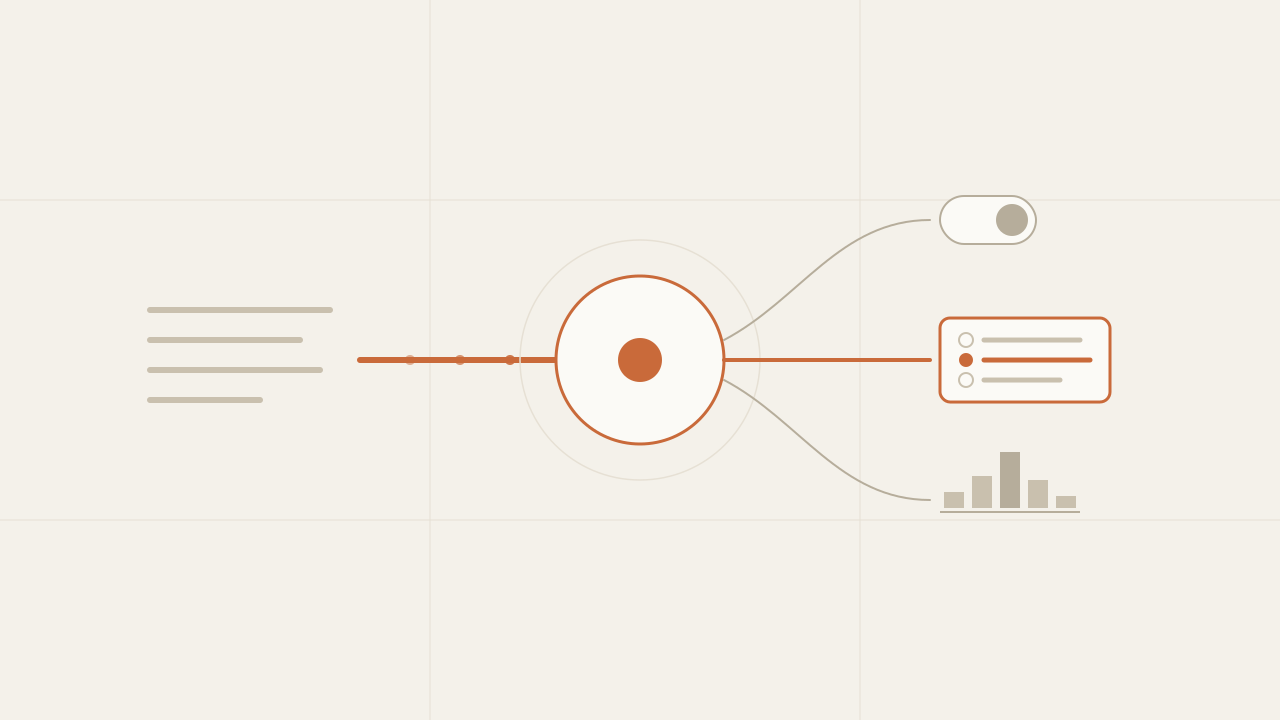
Jev is TypeSafe AI’s first “System One model”: a model that doesn’t generate text. It takes a state and a list of typed questions and returns typed values—a yes or no, an option from a list, a score—with calibrated probabilities. It launched in early access on September 15, 2026, and within a week it became the main topic among those of us building systems with LLMs. I went through the documentation and the first independent analyses to answer what matters in practice: what it is, how to call it, what it costs and where in a real system it makes sense to use it.
TL;DR
- Jev doesn't write: it answers
choice,scoreornoul(yes/no) questions with a value, its probabilities and a confidence level your code can use directly. - It costs 0.042 USD per million input tokens, output is free and the published latency is 70 to 500 ms. It's for classifying, routing, prioritizing and evaluating, not for writing or reasoning.
- Use it as a fast decision layer in front of an LLM: if confidence is high you act, if it's low you escalate to the large model. No one has independently reproduced the benchmarks yet.
In this article:
- Fundamentals — What Jev is · The three question types · Price and speed
- Implementation — Calling the API · Using confidence
- Operation — Where it fits · Limitations
What is Jev and how is it different from an LLM
An LLM generates text token by token. When you use it to decide something—is this ticket urgent? which department does it go to?—you ask for a JSON answer, parse it and validate it in case the model changed the format. A good part of the code around an LLM in production exists only to turn prose into a value the program can use.
Jev removes that step. You send it a state (the context: a message, a document, an agent’s history) and a map of questions, each with a declared type. What comes back isn’t text, but a value of the type you asked for plus a probability distribution. There’s nothing to parse, and the model can’t invent a category that doesn’t exist, because it can only choose among the ones you defined.
TypeSafe AI calls it “System One” after the distinction between fast, intuitive thinking (system 1) and slow, deliberate thinking (system 2). The idea is that current LLMs cover system 2, and that a large share of the decisions a piece of software makes don’t need deliberation, just a fast and measurable judgment. The company is based in San Francisco, was founded by Diogo Almeida—a former OpenAI researcher and one of the co-authors of RLHF—and announced a 40 million USD seed round led by DCVC alongside the launch. The demo that spread the most was Jev playing Doom: it receives a frame and returns the next move, with no commentary.
The three question types: choice, score and noul
The whole API comes down to three primitives. Every question you ask Jev is one of these types:
| Type | What it answers | What it returns | Example |
|---|---|---|---|
choice | One option from a closed list | The chosen option, its confidence and the probability of each option | Which department does this ticket go to? |
score | A level on an ordered scale of 2 to 10 levels | The score, its confidence and the distribution per level | How frustrated is the customer, from 1 to 5? |
noul | Yes or no | The probability that the statement is true, between 0 and 1 | Is the message asking for a refund? |
The difference between the answer and the confidence is the most useful part of the design. The answer says what the model chose; the confidence, computed from the shape of the distribution, says whether you should act on it. If the probability is concentrated on one option, confidence is high. If it’s spread across two or three, it’s low, even when the winning option is the same. An LLM has no native equivalent of that signal: it returns a category with the same apparent certainty whether it’s right or unsure.
How much does Jev cost and how fast is it
The published early-access price is 0.042 USD per million input tokens, and output tokens are free. That makes sense: the output is a number or a label, not a paragraph. For context, in the post on model routing I used DeepSeek V4 Flash as the cheap model at 0.09 USD input and 0.18 output per million; Jev charges less than half for input and nothing for output.
Published latency is 70 to 500 ms end to end. TypeSafe claims that on comparable queries it’s between 40 and 200 times faster and cheaper than a large LLM, and press coverage has repeated different ranges for the same claim.
TypeSafe acknowledges that its evaluations were written by its own team and that the reference answers came from OpenAI and Anthropic models. No neutral harness has reproduced its benchmarks yet. Until that happens, treat the speed and accuracy figures as a hypothesis to measure against your own data.
The price is for early access, not a general-availability rate, and access goes through a waitlist in the TypeSafe console. Before designing a product around that cost, assume it can change.
How to call the Jev API
The API has a single endpoint: POST https://api.typesafe.ai/v1/systemone, with the API key as a Bearer token. The body carries the model (jev-latest during early access), the state and a map of questions where each key is the name you’ll read the answer under. Types are lowercase (choice, score, noul); in uppercase the API responds with a 400.
The minimal request, with curl:
curl -X POST https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jev-latest",
    "state": "I have been trying to connect Stripe for 3 days and the integration keeps failing. I am losing sales.",
    "questions": {
      "is_urgent": { "type": "noul", "instructions": "The customer is losing money right now." },
      "department": {
        "type": "choice",
        "instructions": "Which team should handle this ticket.",
        "criteria": {
          "billing": "Charges, invoices and refunds",
          "technical": "Errors and integrations",
          "sales": "Plans and purchases"
        }
      }
    }
  }'
The response arrives in answers, with one entry per question: answers.is_urgent.noul is a number between 0 and 1, and answers.department carries choice, confidence and probabilities. Wrapped in a function the rest of the code can call:
// lib/jev.ts
const JEV_URL = "https://api.typesafe.ai/v1/systemone";

type TicketDecision = {
  department: string;
  confidence: number;
  isUrgent: number; // probability between 0 and 1
};

export async function triageTicket(text: string): Promise<TicketDecision> {
  const res = await fetch(JEV_URL, {
    method: "POST",
    headers: {
      Authorization: `Bearer ${process.env.TYPESAFE_API_KEY}`,
      "Content-Type": "application/json",
    },
    body: JSON.stringify({
      model: "jev-latest",
      state: text,
      questions: {
        is_urgent: { type: "noul", instructions: "The customer is losing money right now." },
        department: {
          type: "choice",
          instructions: "Which team should handle this ticket.",
          criteria: {
            billing: "Charges, invoices and refunds",
            technical: "Errors and integrations",
            sales: "Plans and purchases",
          },
        },
      },
    }),
  });
  if (!res.ok) throw new Error(`Jev responded ${res.status}`);

  // No text to parse: every answer already comes with its type.
  const { answers } = await res.json();
  return {
    department: answers.department.choice,
    confidence: answers.department.confidence,
    isUrgent: answers.is_urgent.noul,
  };
}
# lib/jev.py
import os
import requests
JEV_URL = "https://api.typesafe.ai/v1/systemone"
def triage_ticket(text: str) -> dict:
res = requests.post(
JEV_URL,
headers={"Authorization": f"Bearer {os.environ['TYPESAFE_API_KEY']}"},
json={
"model": "jev-latest",
"state": text,
"questions": {
"is_urgent": {"type": "noul", "instructions": "The customer is losing money right now."},
"department": {
"type": "choice",
"instructions": "Which team should handle this ticket.",
"criteria": {
"billing": "Charges, invoices and refunds",
"technical": "Errors and integrations",
"sales": "Plans and purchases",
},
},
},
},
timeout=5,
)
res.raise_for_status()
# No text to parse: every answer already comes with its type.
answers = res.json()["answers"]
return {
"department": answers["department"]["choice"],
"confidence": answers["department"]["confidence"],
"is_urgent": answers["is_urgent"]["noul"], # probability between 0 and 1
}<?php
// lib/jev.php
const JEV_URL = "https://api.typesafe.ai/v1/systemone";
function triage_ticket(string $text): array {
$payload = [
"model" => "jev-latest",
"state" => $text,
"questions" => [
"is_urgent" => ["type" => "noul", "instructions" => "The customer is losing money right now."],
"department" => [
"type" => "choice",
"instructions" => "Which team should handle this ticket.",
"criteria" => [
"billing" => "Charges, invoices and refunds",
"technical" => "Errors and integrations",
"sales" => "Plans and purchases",
],
],
],
];
$ch = curl_init(JEV_URL);
curl_setopt_array($ch, [
CURLOPT_POST => true,
CURLOPT_RETURNTRANSFER => true,
CURLOPT_TIMEOUT => 5,
CURLOPT_HTTPHEADER => [
"Authorization: Bearer " . getenv("TYPESAFE_API_KEY"),
"Content-Type: application/json",
],
CURLOPT_POSTFIELDS => json_encode($payload),
]);
$body = curl_exec($ch);
$status = curl_getinfo($ch, CURLINFO_HTTP_CODE);
curl_close($ch);
if ($status !== 200) {
throw new RuntimeException("Jev responded $status");
}
// No text to parse: every answer already comes with its type.
$answers = json_decode($body, true)["answers"];
return [
"department" => $answers["department"]["choice"],
"confidence" => $answers["department"]["confidence"],
"is_urgent" => $answers["is_urgent"]["noul"], // probability between 0 and 1
];
}Compare this with the tolerant parseJSON and the validator from the routing post: none of that is needed here. The API is in early access and field names may change, so take the final ones from the official documentation before going to production. TypeSafe also publishes SDKs for Python and JavaScript if you’d rather not build the request by hand.
How to use confidence to decide when to act
The right way to integrate Jev isn’t to replace the LLM, but to put Jev in front of it. Jev decides the clear cases in milliseconds at almost no cost; the cases where it’s unsure go to the large model, which is slower and more expensive but can reason. A request’s path, in order:
-
The case arrives — a ticket, a message, an agent step
-
Jev responds — value + confidence in under a second
-
Confidence is compared with your threshold
You set the threshold per question, and tune it with real data, not up front.
Is confidence above the threshold?
- Yes — the code acts on Jev’s value: assign, route or discard.
- No — the case escalates to an LLM or a person, and that result is logged to recalibrate the threshold.
It’s the same “try cheap, validate, escalate” pattern from model routing, with one advantage: validation is no longer your own heuristic over the JSON, it’s a signal the model itself provides. Log how many cases Jev resolves and how many escalate. If that percentage drops, either the kind of traffic changed or the threshold is too strict.
Where Jev fits in a system built on LLMs
Jev is useful at any point where your code asks a closed question about a context and needs the answer fast and many times over. The most direct cases:
- Model routing: deciding whether a request can be handled by the cheap model or needs the premium one. Today that decision is usually a rules table or an extra call to a small LLM; Jev is a third option with probabilities included.
- Triage and classification: support tickets, content moderation, lead prioritization, filtering news by relevance.
- Evaluation inside an agent: in an agent loop, each iteration needs a judgment—is the task done? does the result meet the criterion?—and that judgment repeats hundreds of times. It’s the same problem I described in who writes the agent’s tests, but with an evaluator that returns a
noulinstead of a paragraph. - Real-time decisions: bots, games, any system where an LLM’s latency isn’t acceptable.
Where it doesn’t fit: writing, summarizing, extracting fields from free text or any task whose output is content rather than a decision. For that you still need an LLM.
Jev limitations worth knowing
TypeSafe publishes a list of known weaknesses in its Jev 1.13 release notes, and it’s more candid than most launches. Before adopting it:
- 32k-token context. Enough for a ticket or an agent step, short for a long document.
- Maximum of 255 options per
choice. Above that it switches to a slower two-stage method. - It can’t count reliably and struggles with math and date comparison. If the decision depends on “more than 3 incidents” or “before the 15th”, compute that in code and pass it the result.
- It interprets instructions too literally and loses accuracy on multi-step indirect reasoning.
- It degrades with irrelevant context. Send it only what the question needs, not the full history out of convenience.
- It doesn’t explain why. It returns a number with no justification, which makes debugging errors and auditing decisions in regulated domains harder.
The last one weighs the most in production. When an LLM misclassifies, you can read its reasoning; when Jev misclassifies, all you have is the probability distribution. That’s why you should store the state, the question and the full response of every call: it’s the only way to reconstruct an error later.
Frequently asked questions
What is Jev from TypeSafe AI?
Jev is an artificial intelligence model from TypeSafe AI released in early access on September 15, 2026. Unlike an LLM, it doesn’t generate text: it takes a context and typed questions, and returns typed values (yes or no, an option from a list, or a score) along with calibrated probabilities and a confidence level. It’s designed to be consumed by another program, not a person.
Does Jev replace ChatGPT or Claude?
No. Jev can’t write, summarize or reason across several steps, and it doesn’t return explanations. It only replaces the part of a system where an LLM is used today to make a closed decision, such as classifying or routing. The sensible approach is to use it in front of the LLM: Jev handles the clear cases and the LLM the ambiguous ones.
How much does Jev cost?
The published early-access price is 0.042 USD per million input tokens, with output tokens free. It’s an early-access rate and TypeSafe hasn’t confirmed it as general-availability pricing, so it may change. Access is requested through a waitlist in the TypeSafe console.
What does it mean that Jev is a “System One” model?
It refers to the distinction between fast, intuitive thinking (system 1) and slow, deliberate thinking (system 2). TypeSafe AI uses the term for a category of models that make fast, measurable judgments instead of generating reasoning. Jev is the first model in that category.
What are the choice, score and noul types in Jev?
They’re the three primitives of the API. choice picks one option from a closed list, score assigns a level on an ordered scale of 2 to 10 levels, and noul returns the probability that a statement is true. choice and score also include a confidence value between 0 and 1 computed from the probability distribution.
Conclusion
Jev isn’t a faster LLM: it’s a different category of model, one that returns decisions with a type and a probability instead of text. Its real value is in the most repetitive part of an AI system, the closed questions we solve today with an LLM, a JSON response and a validator. If you want to try it without risk, start like this: request access, pick a single decision your system already makes with an LLM (classifying tickets, routing requests), run Jev in parallel on the same traffic without acting on its answer, compare results and confidence for a few days, and only then set the threshold above which you let it decide.
Sensitive data out of the prompt: a TypeScript library written in 39 minutes from its specification
sanitype redacts, masks or drops sensitive data inside the process before a payload leaves for an LLM, a log sink or a third party. How it is implemented in TypeScript.
Read more
Spec-Driven Development in React Native: an MVP that lists the world's earthquakes, specified before writing code
I applied Spec-Driven Development to a React Native MVP that lists the world's earthquakes: the specification decides what goes in the list, and its acceptance criteria become the tests.
Read more
Voice agent that books appointments: ElevenLabs, Cal.com and a backend that never lets the model guess
How I built a voice agent that books 30-minute appointments with ElevenLabs and Cal.com, and why the Fastify backend is what keeps the model from inventing times.
Read more